

At Fresno DevFest, I presented “Leveraging LLMs for Search: Exploring Embeddings.” I used a Pokedex search demo to explain how embeddings can help find related content when the query and result use different words.
What are embeddings?
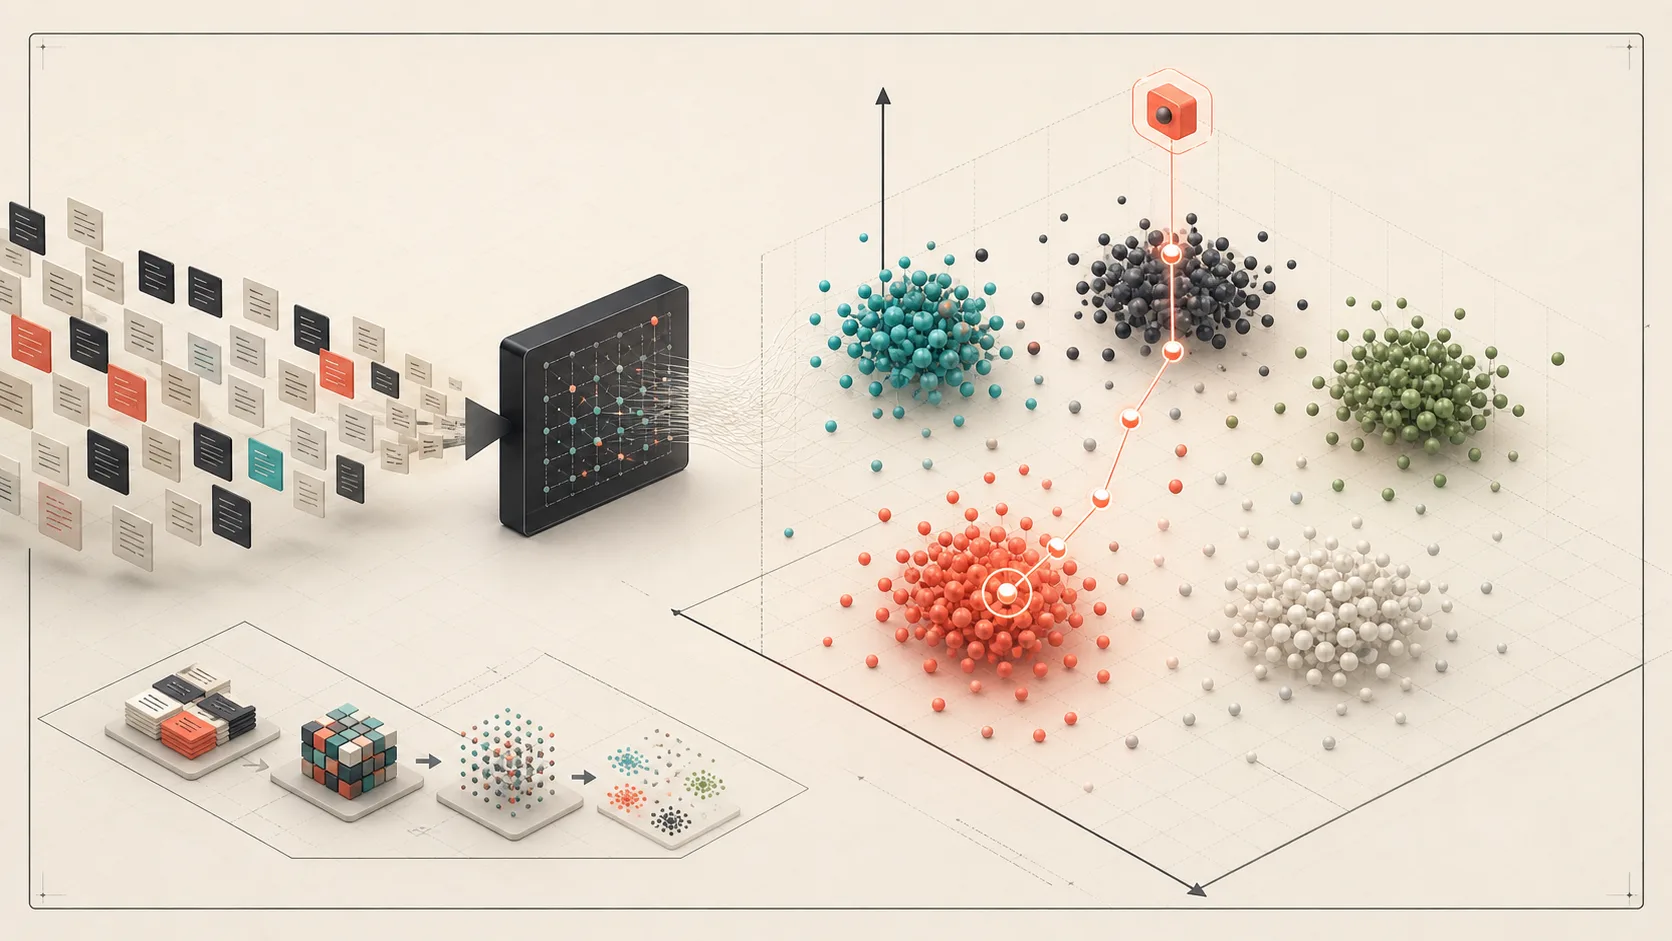
Embeddings show us what the model "sees" in a piece of data. By converting text (or even images) into arrays of numbers, they help LLMs understand relationships, meaning, and context.
These vector representations allow us to:
- Perform semantic search
- Group similar content via clustering
- Power intelligent classification
- Provide focused context to LLMs without full fine-tuning
“King” – “Man” + “Woman” = “Queen” is a famous example of how relationships are preserved in vector space.
Try word2vec live: https://turbomaze.github.io/word2vecjson/
Creating embeddings: APIs, OSS, and LangChain
We explored multiple paths for generating embeddings:
- OpenAI Embedding API — Simple but vulnerable to deprecations or API changes
- LLAMA2 + Huggingface — Open-source, hostable, customizable
- LangChain — A powerful abstraction layer for connecting and switching between models
LangChain simplifies embedding workflows by offering consistent interfaces, while Huggingface offers plug-and-play flexibility with models like CodeLlama and word2vec.
Live demo: Pokedex semantic search
My personal dive into embeddings began with a simple semantic search app—a Pokedex. Rather than keyword-based querying, we can now ask things like "electric rodent" and get Pikachu back thanks to vector-based matching.
We used:
pgvectorwith Postgres- ElasticSearch for full-text + vector hybrid search
SQL-style similarity query:
SELECT 1 - (embedding <=> '[3,1,2]') AS cosine_similarity FROM items;
Try the demo: https://pokedex-seven-sigma.vercel.app
Other directions from the talk
- OpenAI's CLIP — Embed both images and text in the same vector space
- In-browser embeddings — No API required: CLIP Demo
- RAG Pipelines — Use embeddings to inject relevant context into LLM queries
- Smaller, local models — Embeddings and chat agents on your laptop
Fine-tuning vs. context
Embedding-powered retrieval enables a context-first approach. Instead of fine-tuning large models, we can:
- Narrow the context
- Inject relevant, up-to-date info
- Keep cost and tokens under control